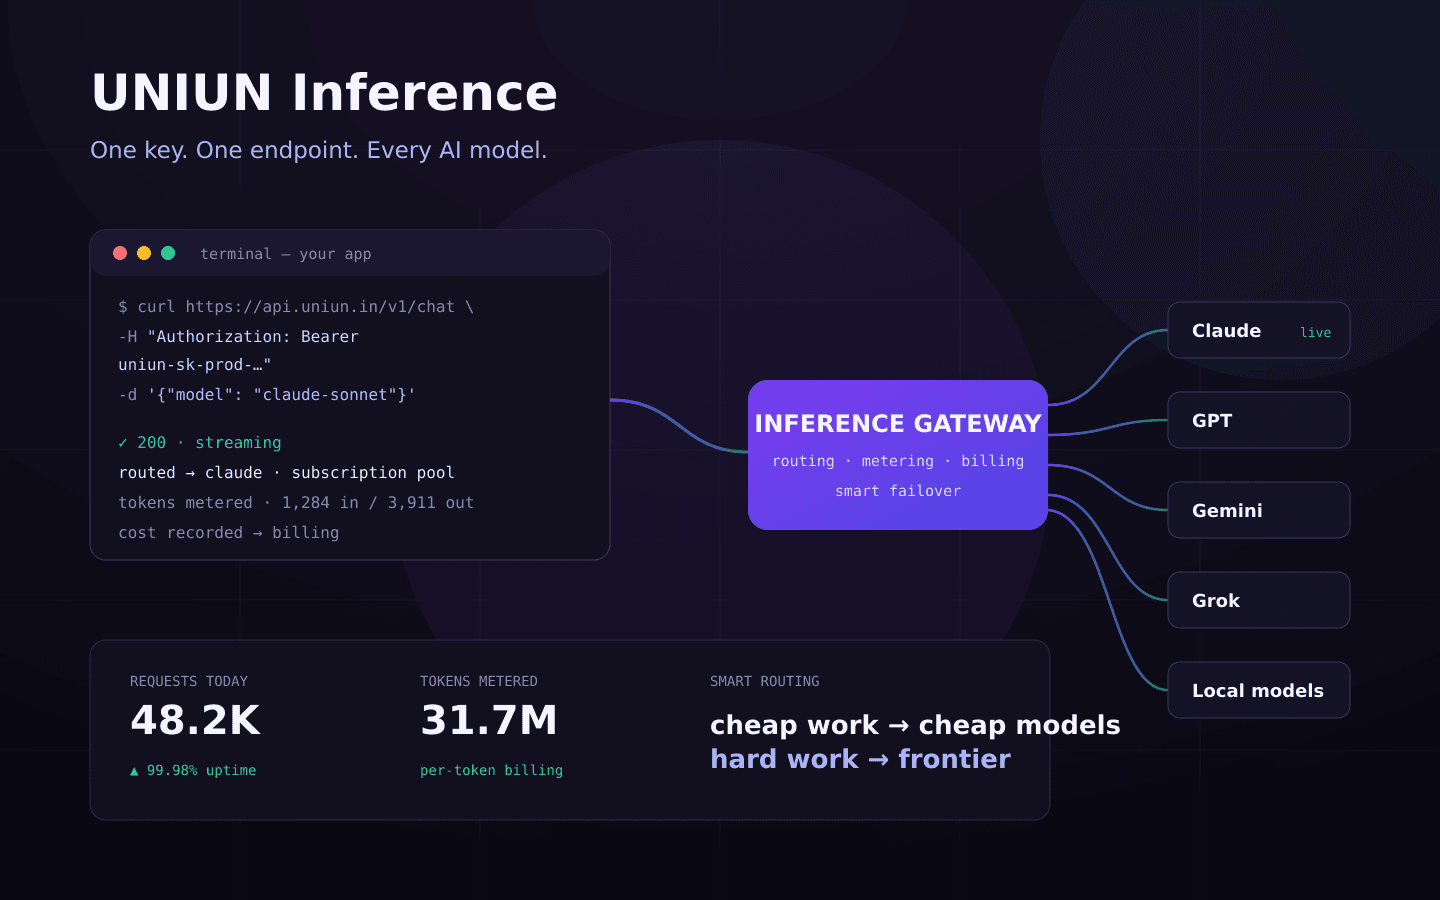
A unified inference gateway that abstracts every LLM provider behind one key — with metering, billing, failover and difficulty-based smart routing.
The problem
Every team wiring up multiple LLM providers repeats the same work: different APIs, auth, pricing, streaming quirks and lock-in. UNIUN Inference is a single abstraction between apps and all providers.
How we built it
Own / Run / Build — a forked Go llm-gateway (OpenAI + Anthropic frontends, routing, failover, OTel), a CLIProxyAPI sidecar that turns subscription logins into API endpoints, and a UNIUN layer for keys, metering, billing and policy. One repo, two containers, one docker-compose up.
What it does
OpenAI and Anthropic wire protocols, both first-class
A backend is a Provider config entry, not a code fork
Difficulty-cascade smart routing — cheap work to cheap sources
DB-backed API keys, per-token metering, rate limits and billing
 Shital Infotech